What is NLP?
The Natural Language Processing NLP (or natural language processing in French) is a field of artificial intelligence and machine learning that makes it possible, via linguistic and statistical algorithms, to understand natural human language.
Its main objective is therefore to enable machines to understand, interpret, and produce human language in a way that is both relevant and useful.
The majority of users have already interacted with NLP without really being aware of it.
This technology is in fact at the heart of virtual assistants such as Oracle Digital Assistant (ODA), Siri or Alexa. It allows them to understand user requests and respond to them in a natural language. In the same way, some messaging applications rely on NLP to analyze the content of a message and automatically offer an appropriate response.
NLP vs NLU vs NLG: Key differences
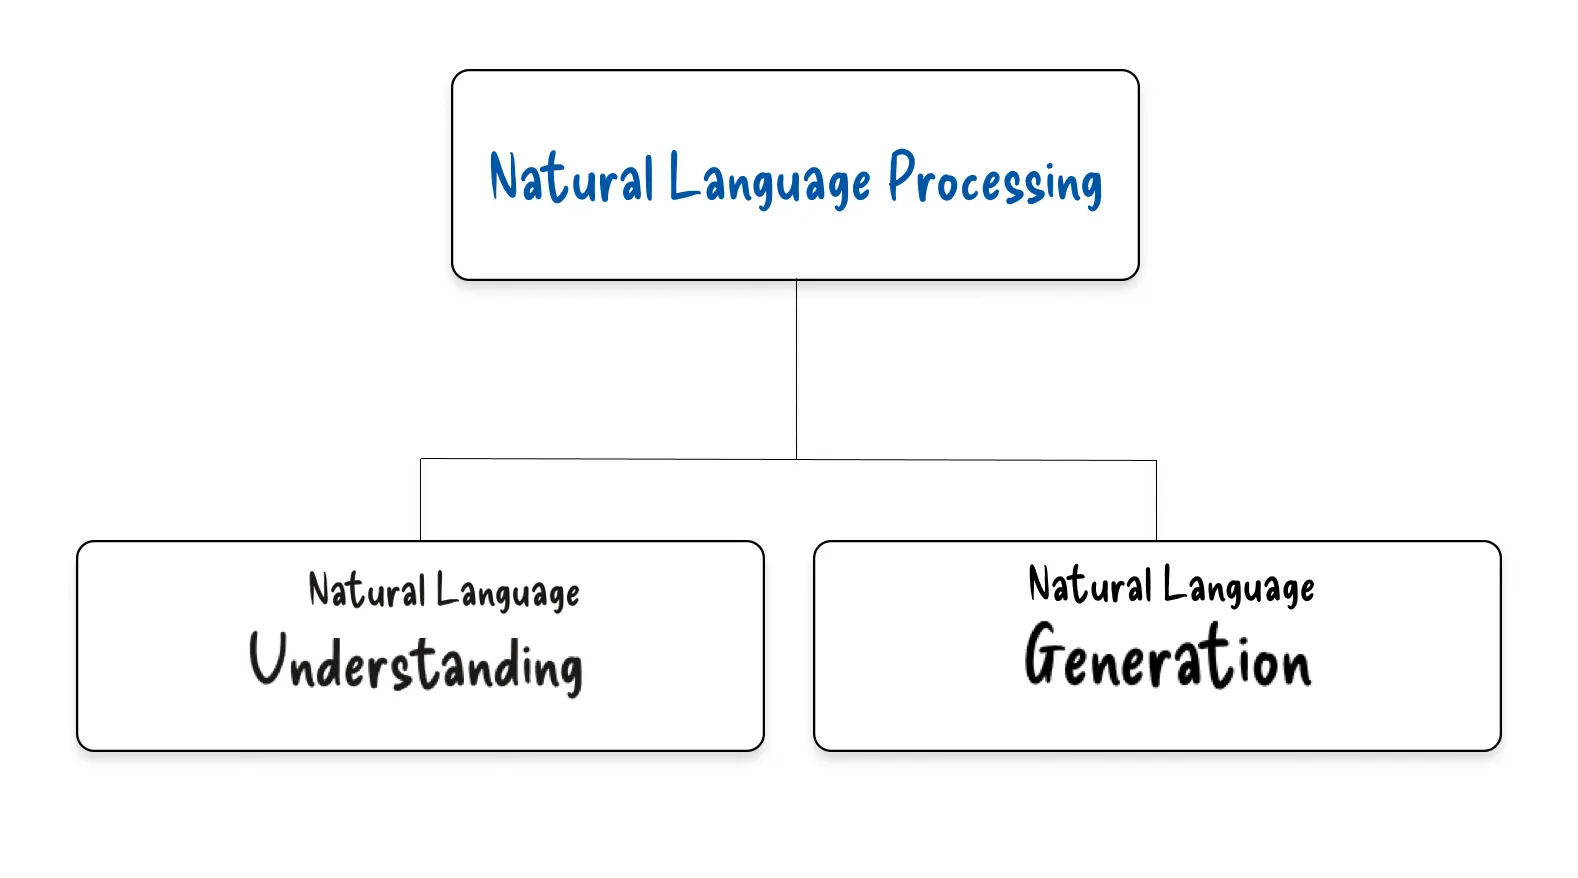
In the world of automatic language processing, several related terms coexist and sometimes lead to confusion. The NLP (Natural Language Processing), the NLU (Natural Language Understanding) and the NLG (Natural Language Generation) actually refer to complementary approaches around natural language.
- NLU (Natural Language Understanding) Corresponds to the capacity of the machines to Analyze and understand The structure and meaning of a sentence expressed by a human. This is the “comprehension” aspect, allowing you to interact with computers using natural sentences.
- NLG (Natural Language Generation) Focuses on the Text production based on data. We Also Talk About “Language out” : the computer generates a verbal description, summary, or explanation in plain language, often using linguistic models or rules (sometimes called Grammar of graphs).
- NLP (Natural Language Processing), more broadly, encompasses both the comprehension and generation of language. It is the field of engineering that aims to build systems that can process, analyze, produce, and manipulate human language.
At the same time, the Computational linguistics (Computational Linguistics , CL) constitutes the scientific field that studies the theoretical and computational aspects of human language, while the NLP focuses on concrete application and the engineering of usable solutions.
The main applications of NLP
Natural language processing covers a wide range of uses and is increasingly shaping our daily practices.
Here is an overview of its most significant uses:
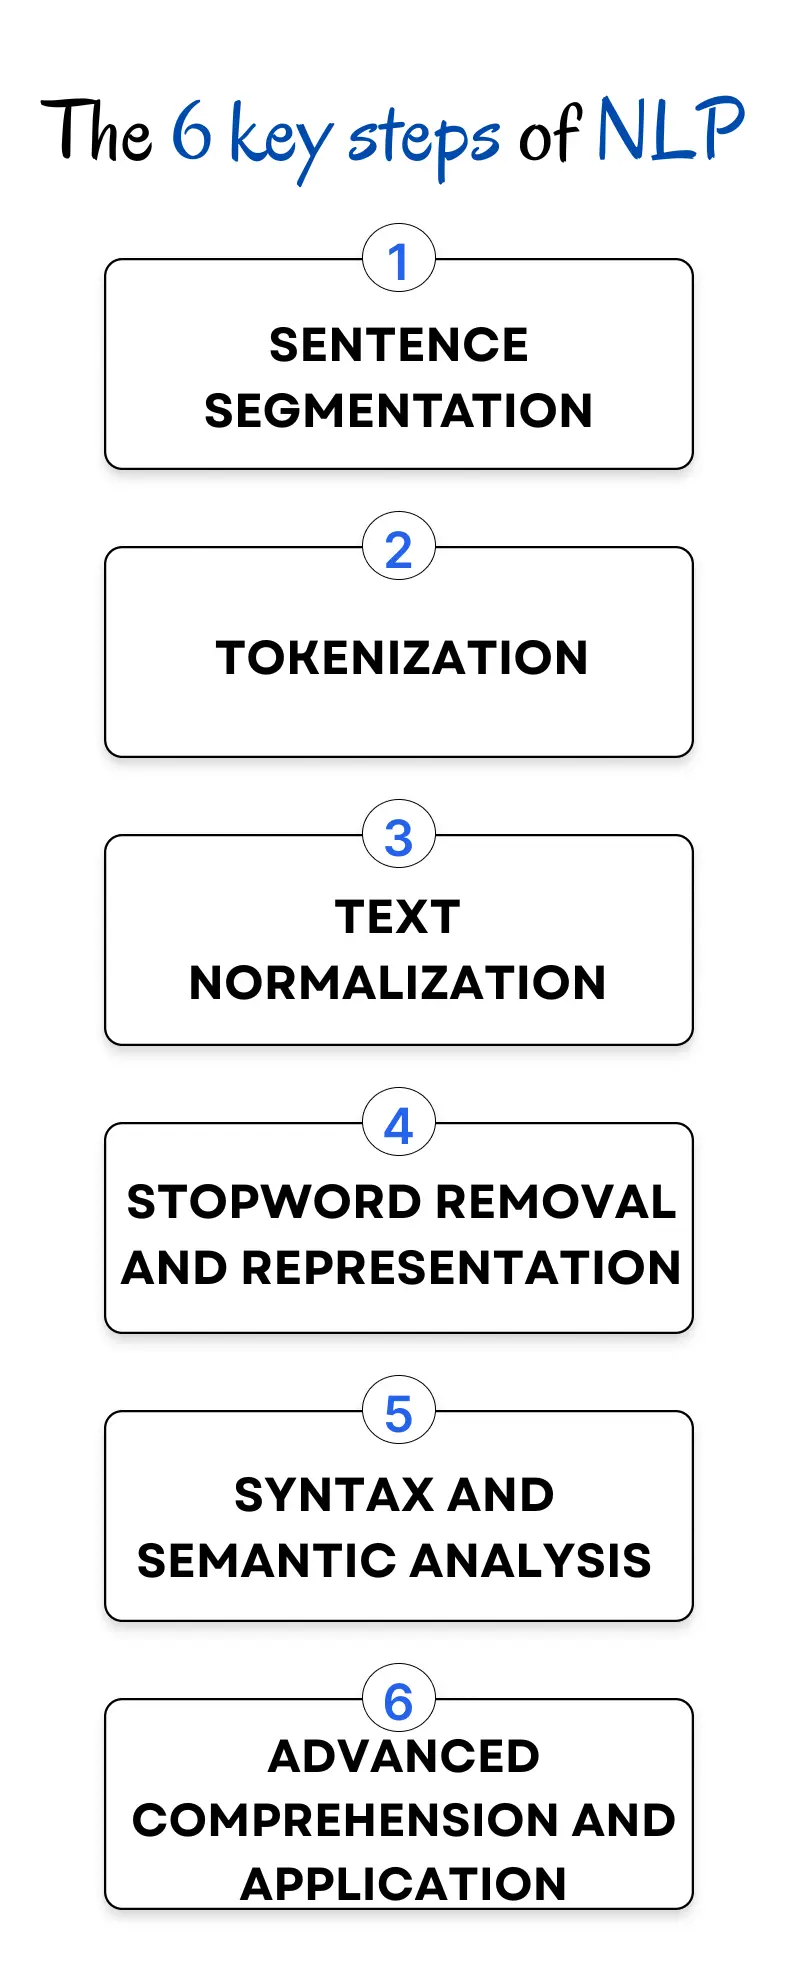
The 6 key steps of natural language processing (NLP)
Natural language processing (NLP) follows a structured pipeline, combining linguistic, statistical, and machine learning techniques. Here are the main steps for turning plain text into actionable information.
1. Sentence segmentation
The process starts with segmentation, which breaks up text into distinct sentences. An algorithm identifies punctuation marks (periods, exclamations, questions) in order to isolate complete units of meaning. It all starts with segmentation, which consists in breaking up text into distinct sentences.
2. Tokenization
Tokenization divides each sentence into elementary units called Tokens : words, subwords, numbers, or punctuation.
This stage prepares the ground for grammatical and semantic analysis.
3. Normalizing the text
The text is then simplified to reduce linguistic variability.
Two main techniques are used:
- Rooting (stemming) : cut the suffixes to keep only the root of the word (“eaten” → “mang”).
- Lemmatization : returns the word to its correct canonical form (“eaten” → “eat”).
This step ensures better consistency in the analysis of textual data.
4. Suppression of stop words and representation
Some Common Words, Said Stop Words (“and”, “of”, “the”), are removed because they provide little information.
Then, the text is converted into usable numerical data:
- Through a Bag-of-Words Model Or a TF-IDF,
- Or via Embeddings (Word2Vec, BERT) that captures the meaning and context of words.
5. Syntactic and semantic analysis
At this stage, the system seeks to understand sentence structure:
- PoS tagging : assign to each word its grammatical function (noun, verb, adjective...).
- Parsing Syntactic : identify subject,verb,complement relationships.
- NER (Named Entity Recognition) : extract entities such as people, places, or organizations.
6. Advanced Understanding and Applications
Finally, the text can be used in concrete applications:
- Sentiment analysis (positive, negative, neutral),
- Automatic summary gold Translation,
- Co-reference resolution (“Jean has arrived. He was tired” → “He” = “Jean”).
It is at this stage that NLP becomes directly useful in business cases: chatbots, search engines, document extraction (OCR + NLP), virtual assistants, etc.
The challenges of NLP
Despite its spectacular advances, this discipline still faces several technical and linguistic obstacles that limit its large-scale deployment.
When OCR meets NLP
Optical character recognition (OCR) is the technology that makes it possible to transform an image containing printed or handwritten text (scanned invoice, signed contract, expense report, form, etc.) into usable digital text.
This step is essential for converting paper documents or image files into structured data, ready to be processed by a computer.
Where OCR is limited to Capture Text Faithfully, NLP adds a layer ofIntelligence and contextual understanding. It is able to classify, contextualize, and extract relevant information, thus transforming plain text into data that can be immediately used by business systems.
In summary: OCR digitizes, NLP includes.
What OCR + NLP integration allows
The combination of OCR and NLP offers several advantages for businesses:
Q&A
What are the most common algorithms used in NLP?
Simple cases still use rule-based or regex approaches, but the standard today relies on machine learning , especially pretrained Transformer networks (BERT, GPT, etc.). Hybrid models that combine retrieval and generation (RAG) are becoming the norm to boost precision and traceability.
What data is needed to train an NLP model?
A clean, representative and diverse dataset, with high-quality annotations aligned to the task. Diversity matters more than raw volume. In sensitive contexts, proper data governance and anonymization are essential.
Which industries benefit the most from NLP today?
Customer service, finance & compliance, legal & insurance, healthcare, e-commerce, marketing, and HR. The common denominator: automating the reading, understanding, and prioritization of large volumes of text.
Can NLP understand irony or sarcasm?
Partially. Models can detect contextual or tonal cues, but performance remains weaker than on factual tasks. For critical decisions, human validation or fallback rules are still recommended.
Is NLP compatible with handwritten documents?
Yes , provided handwriting is first converted to text via HCR or ICR (extensions of OCR). Output quality depends on document preprocessing and confidence thresholds. Targeted human review helps secure ambiguous cases.
How do you measure the quality of an NLP model?
By task: Precision, Recall, and F1 for classification and NER; BLEU/COMET for translation; ROUGE/BERTScore for summarization; Exact Match and F1 for question answering. In production, monitor direct processing rate, human escalation, latency, and data drift , with periodic human reviews for quality assurance.
What are the most common NLP algorithms?
Transformers like BERT and GPT dominate today’s NLP. Hybrid approaches (RAG: Retrieval-Augmented Generation) improve precision and traceability.
What data is needed to train an NLP model?
A clean, annotated, and representative corpus. Quality and diversity matter more than raw size.
Which industries benefit the most from NLP?
Customer service, finance, law, healthcare, e-commerce, and HR , all involving large-scale text understanding.
Can NLP detect sarcasm or irony?
Partially. Context-based models can identify some cues but remain imperfect , human validation is still advised.
Is NLP compatible with handwritten documents?
Yes, via HCR/ICR (extensions of OCR). Result quality depends on preprocessing and confidence thresholds.
How do you evaluate an NLP model?
Metrics depend on the task: precision/recall/F1 (classification), BLEU (translation), ROUGE (summarization). In production, latency and drift are also tracked.